The fastest-adopted AI model can't write a sentence. Here's what it's for.
In its first day on one of the largest model gateways, a model that can't produce a word of prose was adopted faster than any model before it. It answers only the questions you write in advance, with odds attached. This build log is about why that combination (messy text in, a bounded yes, pick or rating out, for a fraction of a cent) may be a new building block for ordinary software, and what it does to the cost of deciding anything by machine. A working demo and two dozen measured runs on my own hardware are the evidence. They earn the argument where they can and mark its limits where they can't.
Instrument and questions: Rick Worthington Analysis and prose: Earl (Claude Opus 5.5), under Rick Worthington's editorial direction
Watch the video at lab.worthington.cloud/entries/cant-write-a-sentence
The question
The fastest-adopted model on a major AI gateway can't write a sentence. What is it for?
On Sep 18, 2026, Vercel published its AI Gateway numbers for a model called Jev, from a company called TypeSafe. Within 24 hours of listing, nearly 13% of the gateway's paid teams had used it. That's twice the first-day share of the GPT-5.6 family and more than six times Claude Fable 5.1's.[1] Those are two of the most capable general-purpose models there are. The one that beat both of them to a team's first request can't produce a word of prose.
Share of paid Vercel AI Gateway teams using it, first 24 hours
Jev
nearly 13%
GPT-5.6 family
half of that
Claude Fable 5.1
under a sixth
Requests per day on OpenRouter, millions
28.2Sep 1852.6Sep 1964.4Sep 2082.4Sep 21
#1 of 556 by requests on Sep 21, but #13 by tokens: many requests, few words each.
Left: Vercel's share of paid teams using each model within a day of launch, the other two drawn from the ratios Vercel gives. Right: daily requests on OpenRouter, the other big gateway, in its first four days.[1, 2]
The other big gateway tells the same story from another angle. On OpenRouter, by its fourth full day, Jev was the most-requested of 556 models, with 82 million requests on Sep 21 alone, while sitting only thirteenth by tokens.[2] Lots of requests with only a few words in each is what decisions look like in traffic. A chat model's traffic runs the other way.
So I put it on the bench: two dozen experiments on public data across four real jobs, plus a small working demo, between Sep 19 and 21, 2026. This page is what it's good for, where it lost, and why the price matters more than the speed.
What the bench showed
Here's what you'd likely assume about a cheap model that only answers closed questions, and what the bench said about each.
“Set the cut-off in the middle, at 0.5.”
Missed 24
24 → 0
real hits missed at the middle cut-off, against none at a cut-off of 0.05. Same model, same questions, same 10,713 repositories.
Jev is a form-filler: your text in, your questions with their allowed answers, the odds on each answer out. It's cheap enough to run on everything (all 10,714 repositories on this site's watchlist for $0.29) and steady enough that a second run over the same repositories changed almost nothing. It's best as a bouncer in front of an expensive model, set to be wrong in one direction only, and as a second opinion, because it fails in different places than chat models do. It loses wherever the call takes judgment. On every job, rewriting the rules moved the score further than swapping the model.
My reading, not measured
What I read into it: the cost of putting a judgment into software has fallen far enough that a lot of decisions nobody could justify building now clear the bar. The old question was whether a decision was worth a machine-learning project. The new one is whether it's worth writing down. That's an argument from one bench, not a measurement.
What's on the bench
Four real jobs from this site's research instrument, run on public data, and one demo built to show the mechanism. Every scored comparison used a fresh sample of 118 to 154 items that no tuning had touched, graded against blind reference labels.[5]
A gate
“Is this repository about AI?”
150 fresh items, scored once
A screen
“Is this paper about AI tooling?”
118 fresh items, scored once
A filter
“Could this be an attack tool?”
10,713 repositories, all of them
A tagger
“Which one of 31 labels fits best?”
154 fresh items, scored once
A demo
An airline chat desk where a decision model reads the customer, plain code ranks 770 packages, and a chat model writes the reply.
Made-up customers and airline, measured by its own instrumentation
About $4 across every model, for every run on the bench.
What was run, on what, and what it cost. The four jobs all read the same kind of short public text. The demo's customers and airline are made up.[5, 6]A
Part A: What it is
Before the results: what this kind of model does, because almost every model people have used writes text back. This one can't.
You don't chat with it. You hand it a form. You send the thing to look at (a message, a ticket, a record, any text) and questions you wrote yourself, each with its allowed answers. It returns an answer to every question, with the odds attached.[4]
In: the text
“I'm flying for work and don't want to use my miles. I have a large suitcase I need to bring and I need my leg room. What's the best deal I can get for a direct flight?”
In: questions you wrote, and the odds out
Traveling for business? yes or no0.96
Asked for a nonstop? yes or no0.98
Asked for legroom? yes or no0.96
Wants to use miles? yes or no0.10
and 20 more
Out: the odds on each
0.96
0.98
0.96
0.10
One real turn from the demo: a customer's sentence and four of the questions asked about it, with the odds that came back. The answer can only ever be one of the options you supplied.[6]
Because the answer can only be one of your options, it can't invent a category, wander off topic, or pad a reply. What comes back is a number your own code can act on: keep it, drop it, sort by it, or send the item to something smarter. There are three shapes of question, and everything on this page is built from them.
Yes or no
“Is this email a complaint?”
yes0.91
no0.09
Pick one
“Which queue should take this ticket?”
billing0.72
technical0.21
sales0.07
Rate it
“How urgent is it, on four described levels?”
10.05
20.15
30.60
40.20
The three question types, as TypeSafe's documentation defines them, each with a made-up example.[4]
The name is a clue. Jev is short for William Stanley Jevons, the economist who noticed that as steam engines got more efficient, Britain burned more coal, not less. Cheaper work meant more work was worth doing. TypeSafe says that's exactly why it chose the name.[4] Make a judgment cheap and people start making it everywhere. At $0.042 per million tokens read, with nothing charged for the answer, a paragraph costs a few millionths of a dollar.[2]
B
Part B: Why the price matters
This part is my argument, so it's on graph paper. The parts after it are the measurements it rests on.
My reading, not measured
Software has had four ways to make a decision. What separates them is what a team had to have before it could ship one.
Needed before it shipsSpeedCost per decisionThe catch
Written rules in code
Someone to write every case by hand
Instant
Free
Can't read meaning
A custom predictive model
Data, labels, a team to train it, upkeep
Fast
Costly to build, cheap to run
Has to be worth a project
A chat model
An afternoon of prompting
Seconds
The most per decision
Prose to parse, varies run to run
A decision model
A few written questions
Under a second
A fraction of a cent
Only answers what you asked
Four ways software decides, by what each needed before it could go into production. My reading, not a measurement: zero-shot classifiers, rerankers and embeddings answered bounded questions before this, and the ladder isn't about who invented what.
A custom predictive model can answer fuzzy questions, like whether a customer is about to leave or where a ticket should go. But it needs historical data, labeling, someone to train and check it, and upkeep when the world drifts. So a classifier had to be worth enough to pay for its own construction, and most questions never made the cut. A chat model brought the effort down to an afternoon, but for a bounded question it's a lot of machinery: slow, relatively expensive, and producing prose that has to be parsed and checked.
A decision model sits in the gap: messy text in, a bounded answer with odds out, at the speed of ordinary application code and at a price closer to a database lookup than to a model call.
What it would be worthWhat it costs to build and keepThe old line: worth a projectThe new line: worth writing down
Built under the old line
Clears the new line
Still not worth it
$0.29 to ask 9 questions of all 10,714 repositories, once
about $17 to screen all 290,240 research abstracts, priced from a measured sample
Ideas for a classifier, by what each would be worth and what it costs to build. Only the ones above the line get built. The line is drawn, not measured. The two prices on the tape are measured: one full pass over every repository, and the priced screen of every research abstract.[5]
My reading, not measured
The claim that matters is that the threshold for building one falls, which is more than classifiers getting cheaper. At $0.29 to ask nine questions of 10,714 repositories, a check runs on everything rather than on a sample, and deciding to build it stops being a project decision and becomes a pull request. A field report later tested what AI changed about building software versus buying it. How many classifier ideas were never built because they didn't clear the old line? One bench can't answer that. It can say where the line sat on the jobs I measured, and it was lower than I'd have guessed.
It works alongside code, predictive models and chat models, and connects them. The model turns meaning into numbers, and ordinary software sorts, filters and routes on those numbers. Parts C and D are the two shapes I measured: decision model then plain code, and decision model in front of an expensive model.
Decision model
Plain code
Chat model
Built: Part C
Messy textTurns it into numbersRanks, sorts, routes
Built: Part D
Messy textDecides what to pass alongReads only what survives
Sketched
ReadsDecidesWritesChecks the writing
Three ways to wire it. The first two were built and measured below. The third is the full chain, sketched.C
Part C: See it decide
The first wiring, built end to end: a decision model reads what a customer said, plain code decides, and a chat model only does the talking.
The demo is a chat desk for a made-up airline, NorseStar Air, and you play the customer. Behind the chat sit the things the airline could offer (a cheaper fare, a better seat, a miles upgrade, a free checked bag, a nonstop), which combine into 770 buyable packages. A short scoring formula ranks every one of them. It's ordinary code, eligibility rules and a few weights, with no model in it. It knows the customer's status, miles balance and usual cabin. In the first version it couldn't understand a word the customer typed.
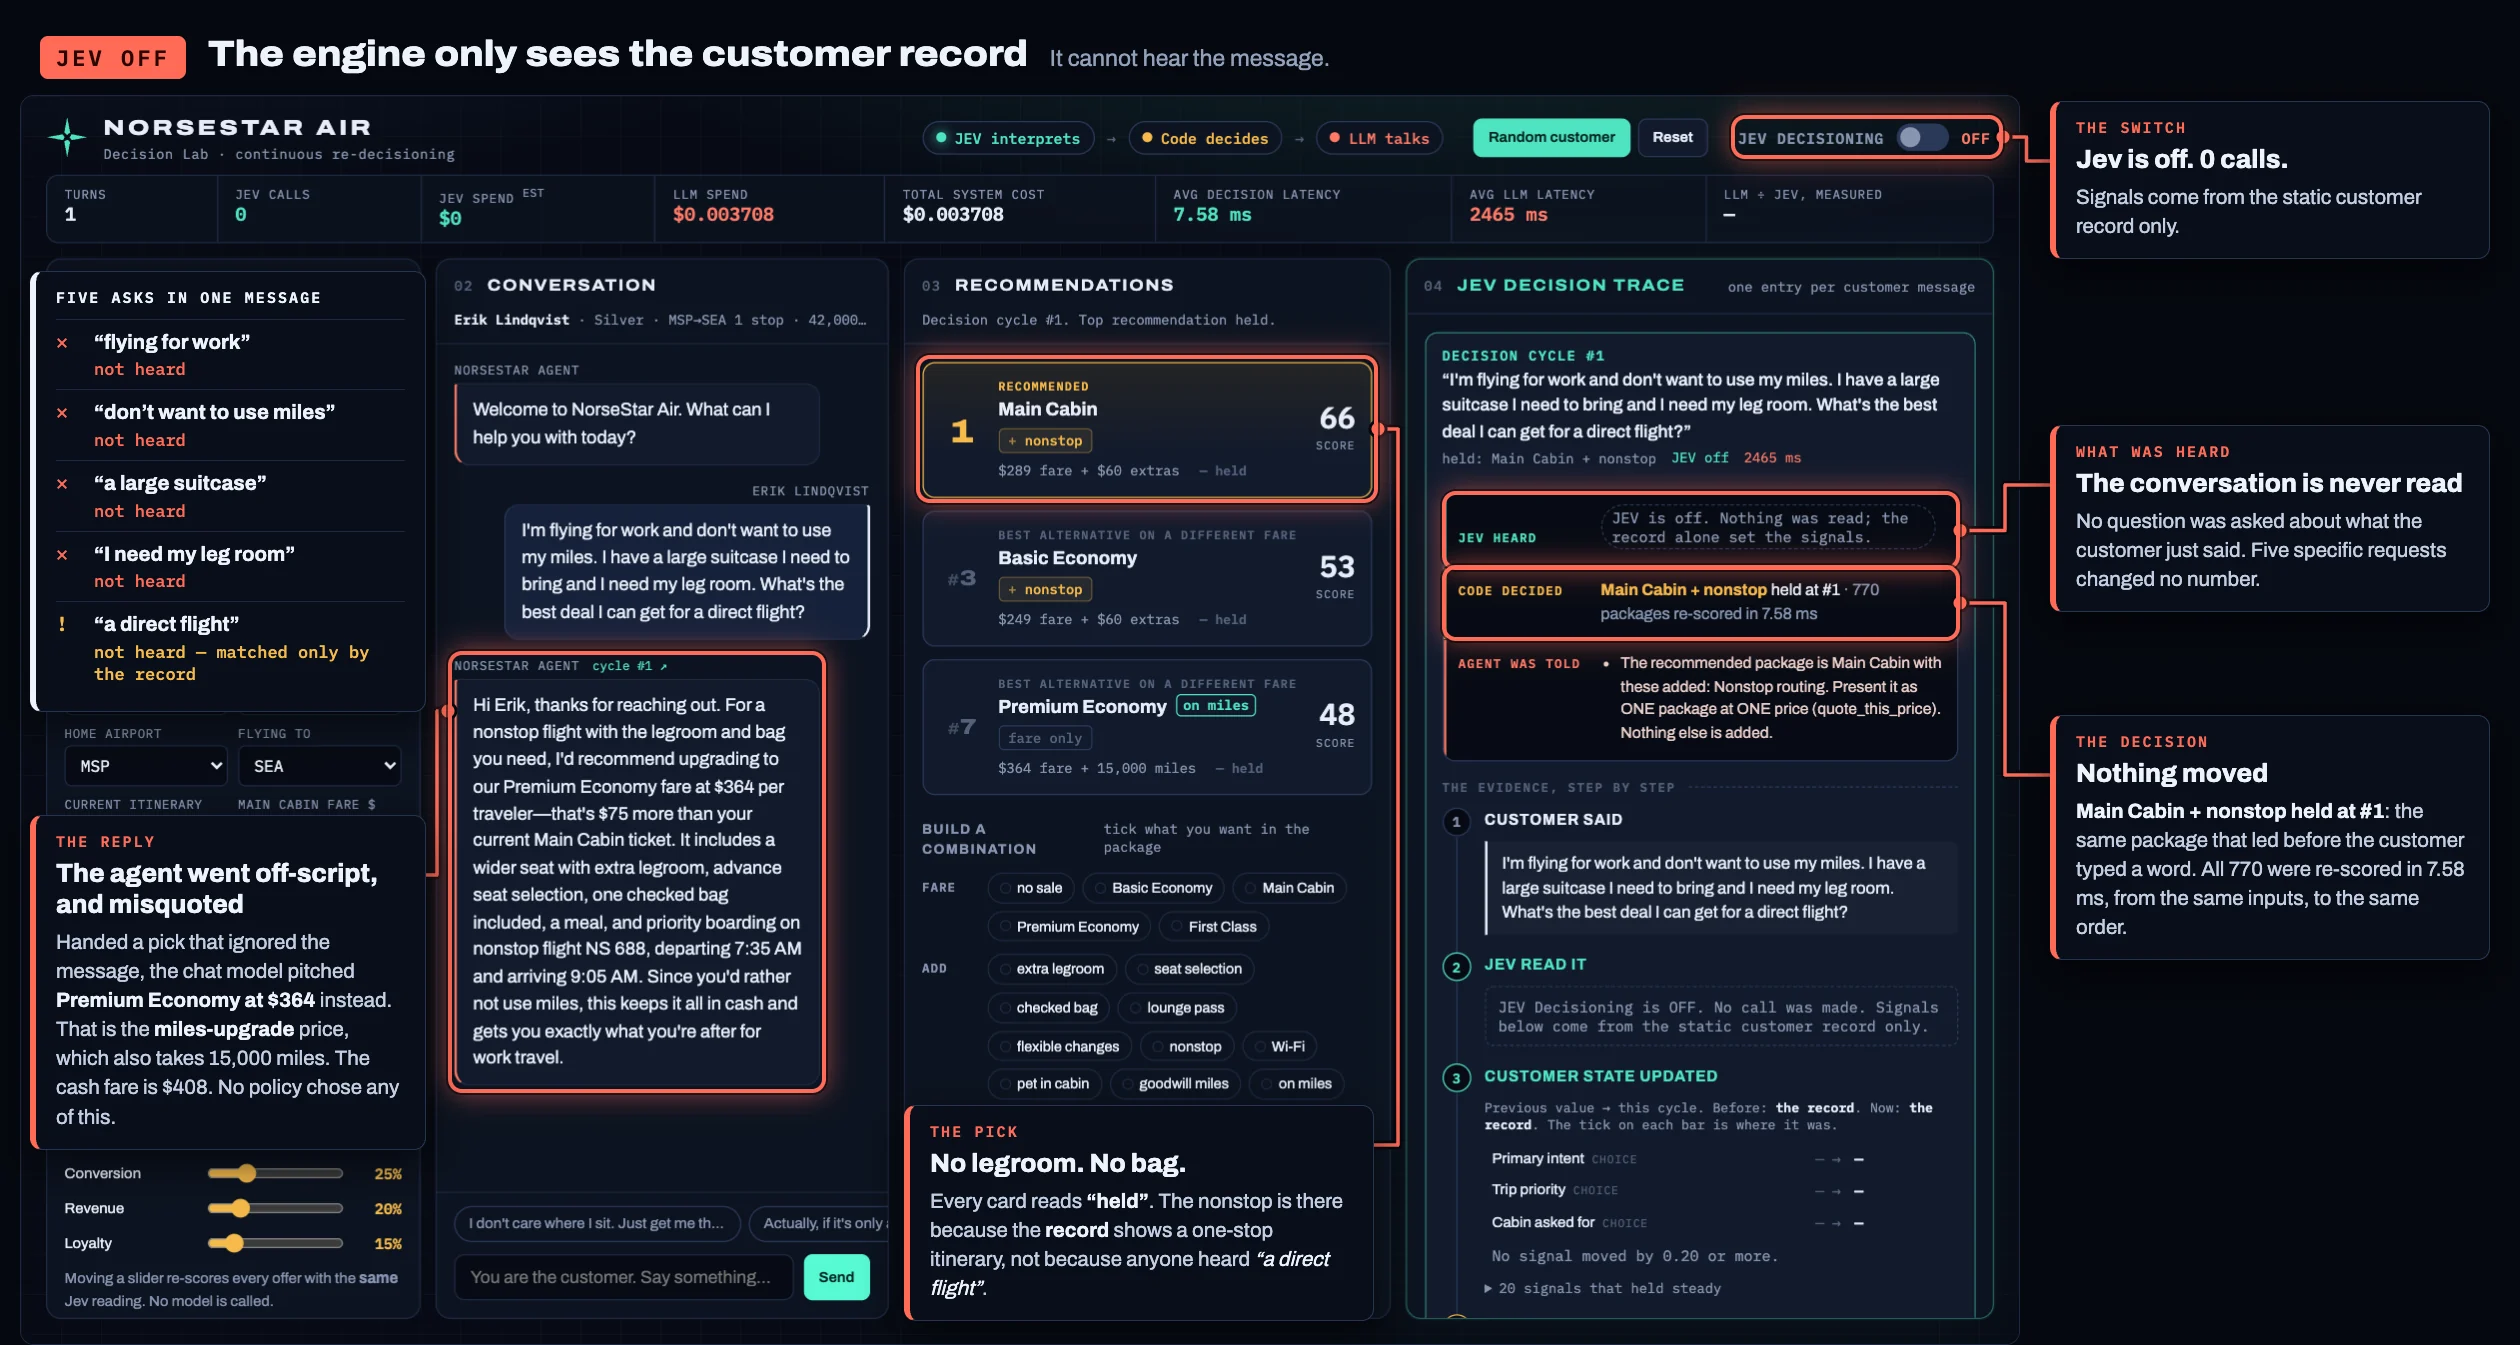
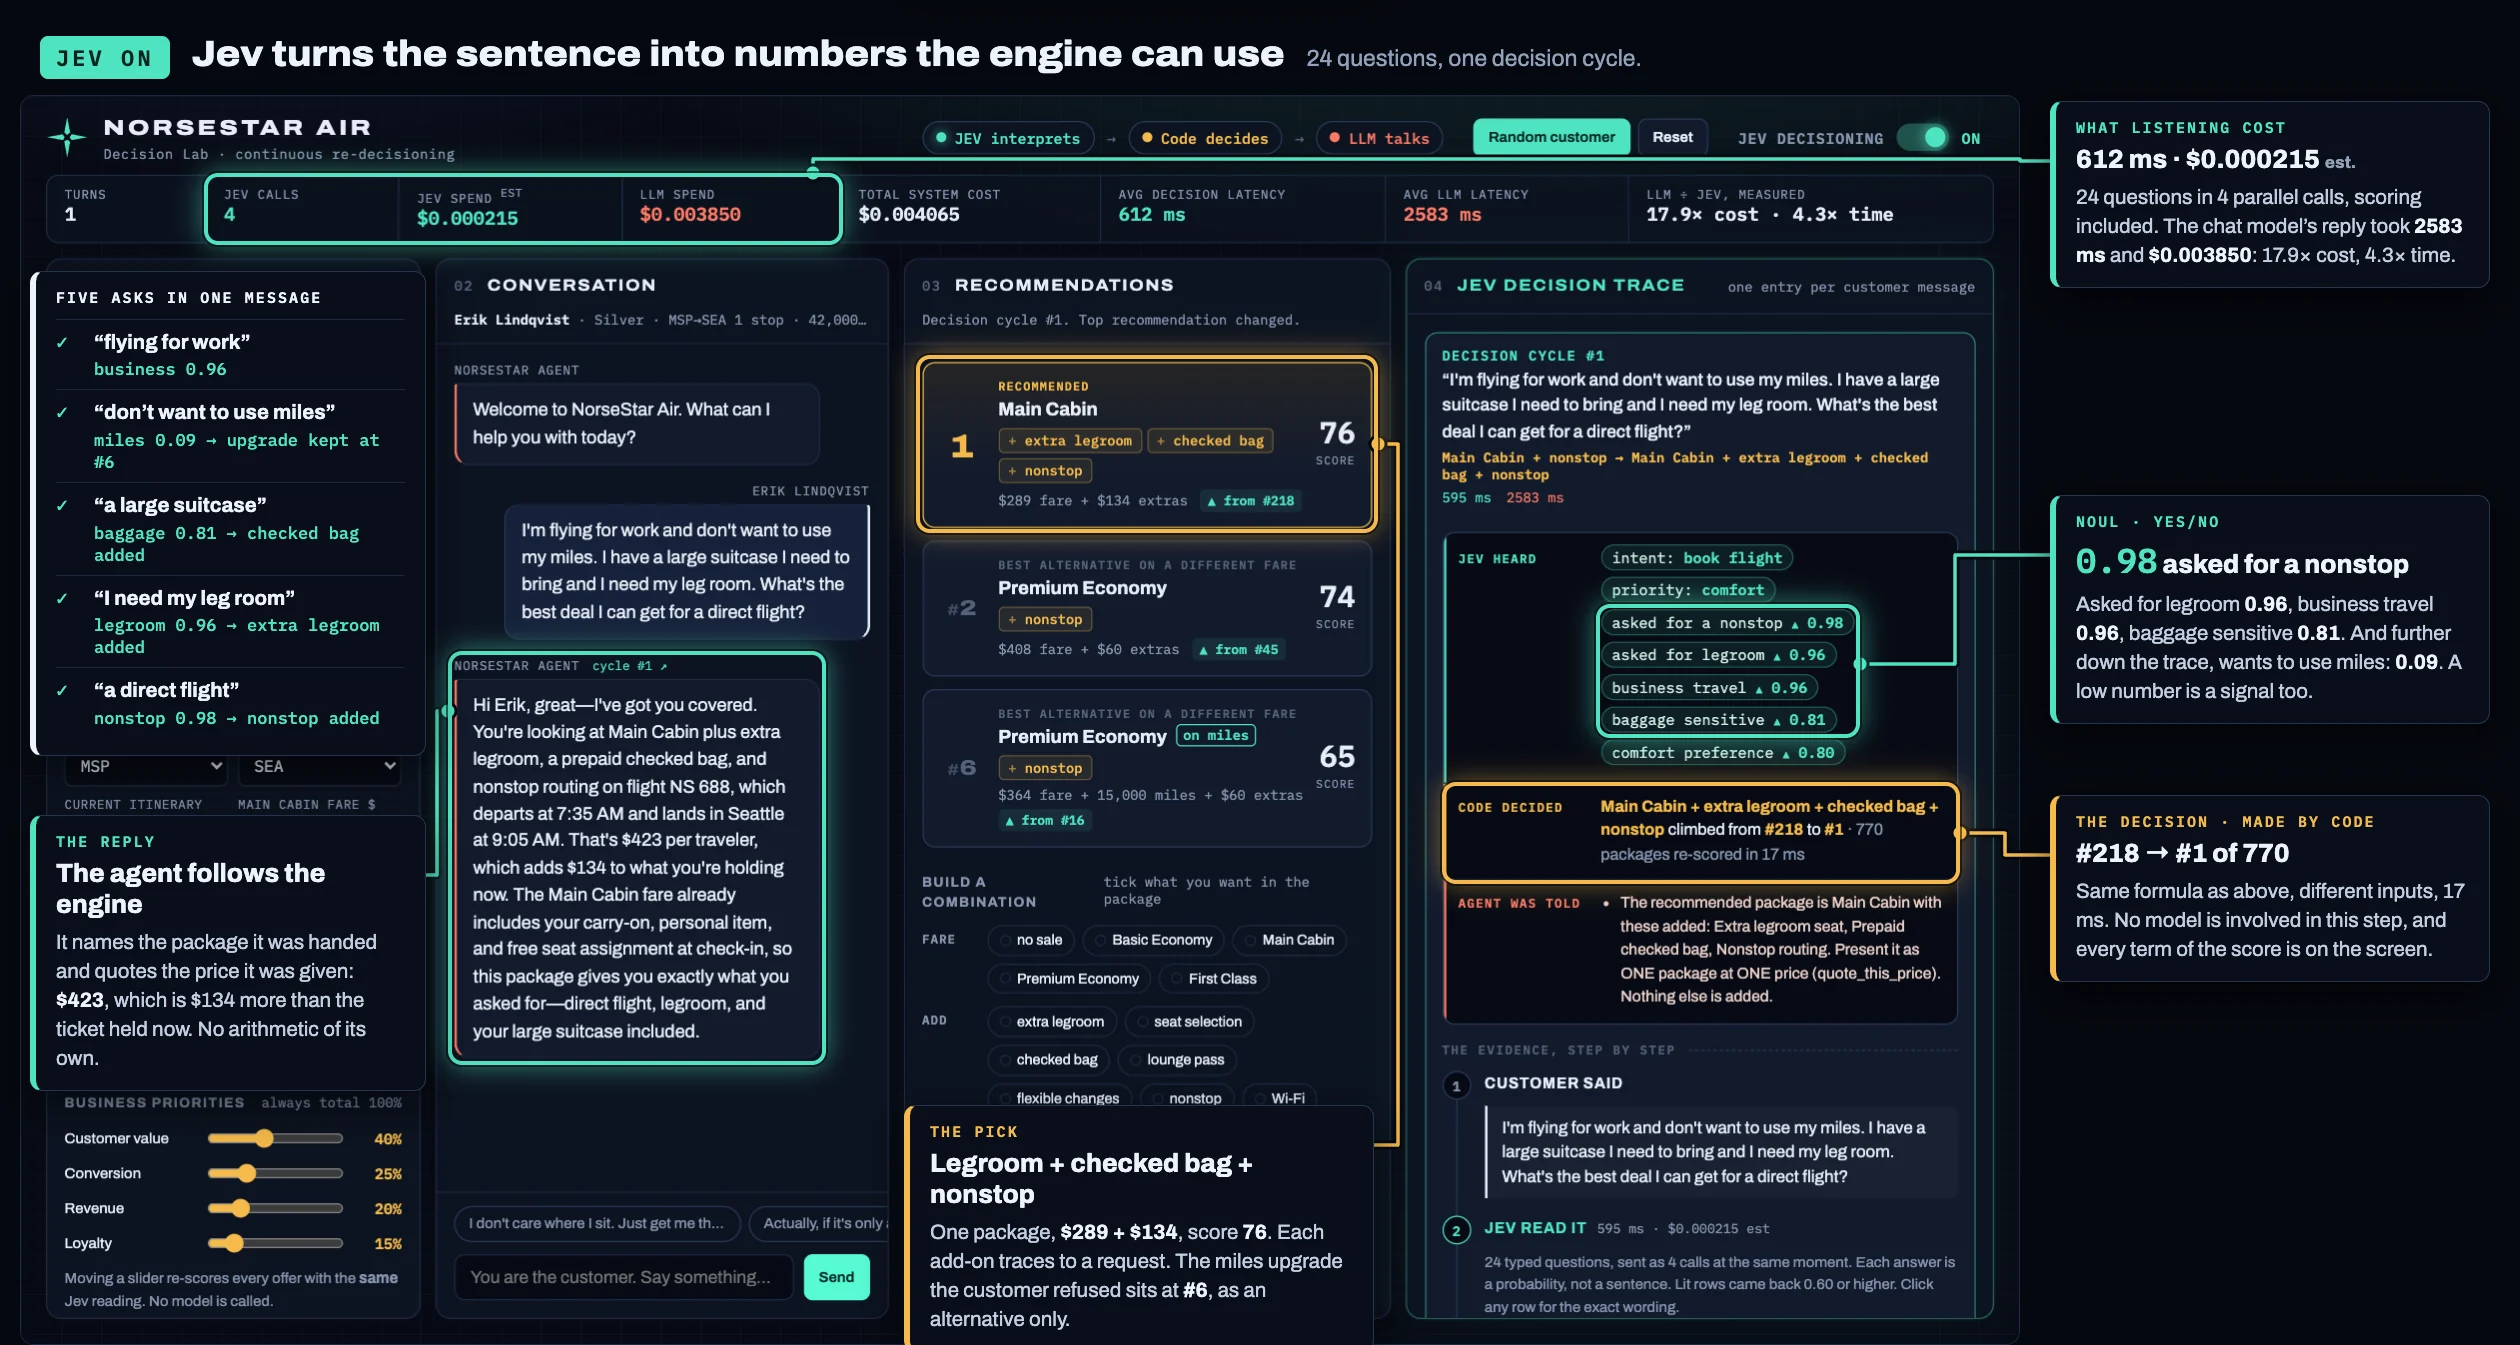
One customer, one sentence: "I'm flying for work and don't want to use my miles. I have a large suitcase I need to bring and I need my leg room. What's the best deal I can get for a direct flight?"
Switched offSwitched on
The same message, the same scoring code, the same 770 packages, with the decision model switched off and on. Screens from the demo's own instrumentation, one turn for one made-up customer.[6]
f1modeledOne turn, one made-up customer
One switch moved the right package from #218 to #1.
MeasuredWith the decision model reading the message first, the package the customer asked for went from #218 to #1 of 770, and no model made the pick.
Measured or publishedFrom the runs and the record
Rank of the package the customer asked for, of 770
#770#1Off: #218On: #1
This turn, reading the message against writing the reply
Jev reads24 questions
595 ms · $0.000215
Chat model writesthe reply
2,583 ms · $0.00385
The step that made the decision used no model: the ranking is arithmetic, and every term of it is on the screen.
Where the winning package ranked, and what reading the message cost beside writing the reply, on this turn.[6]
For whoever builds it: Let the model turn the sentence into numbers, and let code you can read make the decision.
Evidence and objections
Measured Twenty-four questions about the message, written in advance, answered in 595 ms as four parallel calls, for about $0.000215 (estimated from the token count at list price). Re-scoring all 770 packages took another 17 ms. The chat model's reply took 2,583 ms and cost $0.00385, as billed. On this turn the reply cost 17.9 times as much and took 4.3 times as long.[6]
Measured The winner was Main Cabin with extra legroom, a checked bag and a nonstop. The refused miles upgrade sits at #6, as an alternative only.
Measured Nothing in the scoring changed. It was handed different inputs. Swapping the chat model wouldn't change the decision. Swapping the decision model would only change the inputs.
Objection, stated: a chat model alone could have read that sentence. What it couldn't do is hand a number to a formula written before it existed, which can then be tested and argued with line by line.
f2moderateSeen twice, in two builds
A fluent reply covered for a wrong decision.
MeasuredWith the switch off, the code led with the miles upgrade the customer had just refused, and the chat model quietly pitched something else. The reply read fine.
Measured or publishedFrom the runs and the record
“…don’t want to use my miles…”
The code picked
A miles upgrade
Just refused
The reply pitched
Something else, at the wrong price
Reads fine
The two disagree, and only the trace shows it. The customer sees a good reply.
What the code picked and what the reply said, on the switched-off screen. Only the demo's trace shows the two disagreeing.[6]
For whoever builds it: Show the decision beside the reply, and check that they match.
Evidence and objections
Measured Switched off, the code could only see the record, and the record showed a healthy miles balance. Every row of the ranking read "held": nothing moved when the customer spoke.
Measured The same thing happened in an earlier build: the code ranked a $420 upgrade first for a customer who'd said "another hundred bucks," and the chat model pitched the $119 option on its own. The offer was different, and the reply covered for it the same way.[6]
Why it matters: nothing on the customer's side of the screen shows that the decision under a fluent reply was wrong.
Reading the customer on every turn changed the pick when they changed their mind.
MeasuredOne message apart, the customer's price sensitivity went from 0.99 to 0.35, and the top pick moved with it. In the first build's scripted run, it changed on seven of eight turns.
Measured or publishedFrom the runs and the record
Turn 1
“I don't care where I sit. Just get me there cheaply.”
Price sensitivity
0.99
Values comfort
0.01
Top pick: The cheapest fare
Turn 2
“Actually, if it's only another hundred bucks I'd rather be comfortable.”
Price sensitivity
0.35
Values comfort
0.67
Top pick: Premium Economy, $119 more
In the first build’s scripted run, two four-turn conversations, the top pick changed on 7 of 8 turns.
Two of the twenty-four answers, on the first two turns of one scripted conversation.[6]
For whoever builds it: Decide again on every message, because people change their minds mid-conversation.
Evidence and objections
Measured Turn one: "I don't care where I sit. Just get me there cheaply." The cheapest fare ranked first. Turn two: "Actually, if it's only another hundred bucks I'd rather be comfortable." Comfort went from 0.01 to 0.67 and the pick moved to Premium Economy, at $119 more.
Why it's affordable: the reading step is a fraction of a cent and a fraction of a second, so it can run on every message. A frontier model reconsidering each turn would be the slowest and most expensive thing on the page.
f4strongVisible on both builds' screens
It only hears what you wrote a question for.
MeasuredThe customer asked for a direct flight, and in the first build the nonstop fell from #2 to #8. None of the thirteen questions asked about one.
Measured or publishedFrom the runs and the record
First build13 questions, none about a nonstop
#2#8fell once the model was on
RebuiltOne question and one weight added
0.98heard as “asked for a nonstop”; the winner carries it
The nonstop's rank, before and after one question and one weight were added. The rebuilt demo hears the same sentence as "asked for a nonstop" at 0.98.[6]
For whoever builds it: Write the question you might not need. A missing question is invisible from the outside.
Evidence and objections
Measured The repair was one question and one weight, riding along in a request that was already being made. On the rebuilt demo the same sentence comes back "asked for a nonstop" at 0.98, and the winning package carries the nonstop.[6]
f5moderateOne probe, then one fix
For a rating, use the spread of odds, not the average.
MeasuredAn early five-level price scale came back split 0.49 and 0.51 across two levels that were both true. Averaged, it landed on the middle level, "no clear signal."
Measured or publishedFrom the runs and the record
Another level0.49Wants to keep cost downaverage lands hereNo clear signal0.51Will pay more for something they valueAnother level
The early scale had five levels. The other three got almost no weight.
The odds on each level of the early scale, for "another hundred bucks," and where averaging them lands.[6]
For whoever builds it: Treat a rating's odds on each level as separate signals. Don't collapse them back into one number.
Evidence and objections
Measured The two levels were "will pay more for something they value" and "wants to keep cost down." The fix had two halves: rewrite the levels so they can't both be true, and have the code ask what this customer would pay at each level rather than collapse the answer to a single figure.
D
Part D: Where it earns its keep
The second wiring: a cheap model in front of an expensive one, deciding only what to pass along. This is the job it's best at.
This site publishes rankings of public code repositories, and by policy doesn't name tools built for attacking systems. That's ten thousand repositories, refreshed constantly, with a judgment call on each. Before this, an expensive reader model read every one. A later build asked whether a free model on a Mac mini could take that first look instead.
f6strong10,713 repositories, two settings
The obvious cut-off missed 24 real hits. A low one missed none.
MeasuredAt 0.5 it missed 24 of the 212 attack tools. At 0.05 it missed none, and still turned most of the work away.
Measured or publishedFrom the runs and the record
Cut-off 0.50passes 205 of 10,713 to the reader
Missed 24 of 212
Cut-off 0.05passes 2,349 of 10,713 to the reader
Missed none of 212
Passed to the expensive reader
A real hit, caught
A real hit, missed
What each cut-off passed to the expensive reader, and how many of the 212 real hits it missed. Model, questions and repositories were identical in both rows.[5]
For whoever builds it: Set the cut-off by what you can afford to miss, hand the survivors to something that can actually read, and keep those two numbers as separate settings in your code.
Evidence and objections
Measured At 0.05 it passed 2,349 of 10,713 repositories and missed none of the 212. At 0.50 it passed only 205 and missed 24.[5]
Measured A full sweep wired this way cost 73% less, with the same 212 of 212 caught. The hourly run only looks at what's new, where the saving is under a cent. The better argument for wiring it this way is headroom, not money.
f7moderate154 items, against two blind passes
As a filter in front, it made the whole job better and cheaper than the frontier model alone.
MeasuredJev narrowing the work for other models reached 89.6% for about $2.55 per thousand, against Claude Opus 5 alone at 85.1% for about $5.77.
Measured or publishedFrom the runs and the record
Drops what isn’t AICheap chat model tagsTags again, flags disagreementsCareful model, flagged only
Agreement with the blind reference, and the price per thousand items
The chain
89.6% · $2.55
Claude Opus 5 alone
85.1% · about $5.77
The tagging job, wired as a chain: Jev drops what isn't about AI, a cheap chat model tags the rest, Jev tags it again on its own, and only the items where they disagree reach a careful third model.[5]
For whoever builds it: Ask the cheap model to narrow the job, and leave the deciding to something that can read.
Evidence and objections
Measured This is a job Jev loses outright on its own (f10). The chain is better and cheaper than the frontier model because Jev narrows the work well, even though it does the job itself badly.[5]
The bug no test caught: the cut-off that filters and the one that flags a disagreement were the same variable in the shipped script. An item can only survive the filter by scoring above it, so almost every survivor read as a disagreement: 1,854 sent for expensive review instead of about 70. It was found by watching a live log during a production rehearsal.
f8moderate154 items, 20 errors to catch
A model that fails differently is the better second opinion.
MeasuredFlagging every item where Jev and the chat model disagreed caught 15 of the chat model's 20 errors. A second chat model caught 6, at eight times the price.
Measured or publishedFrom the runs and the record
Jev's flag, as wiredflags 35% of items
15 of 20
Jev, asked properlythe correct pick-one question
11 of 20
A second chat model8× the price
6 of 20
The chat model's 20 errors, and how many each checker flagged. Jev's flag covered 35% of the items.[5]
For whoever builds it: Pick a checker built on a different principle. Two similar models agreeing proves much less.
Evidence and objections
MeasuredAsking it properly made it a worse checker. Switching Jev to the correct pick-one question made it agree with the chat model more often, so it caught 11 of 20 instead of 15. Where a part's job is to disagree, the clumsier wiring is the right choice.[5]
MeasuredThe expensive judge wasn't worth its premium. Of twelve model and calling-style combinations tried for the final step, Claude Sonnet 5 at $3.87 per thousand got 43 of 54 right and Claude Fable 5.1 at $15.93 got 44. One item at four times the price is a tie at this size.
f9strongTwo full passes over 10,714 repositories
At full coverage it was cheap, accurate and steady.
MeasuredRun twice over the whole watchlist, 8 answers of 10,714 changed. A chat model doing the same job returned between 99 and 108 hits for identical input.
Measured or publishedFrom the runs and the record
Jev, the whole watchlist run twice
Answers changed
8 of 10,714
A chat model, the same job on identical input, five runs
9510010511099102103106108
Hits returned per run. Every run read the same repositories.
Repeat runs over identical input: how many answers changed for Jev, and the hit counts five chat-model runs returned.[5]
For whoever builds it: Believe the price, then check how often the question gets asked. Cheap only matters at volume.
Evidence and objections
Measured On the "is this repository about AI?" gate, on fresh data, it agreed with the reference 98.7% of the time, where Claude Opus 5 reached 95.9%. On research abstracts it agreed 95.8% of the time, against 81.4% for the keyword rule it would replace.[5]
Measured Fourteen questions per item cost about what two did. Everything asked in one request is answered against one reading of the text, so the extra question is nearly free.
Objection, stated: on a job asked a few hundred times a month, saving 90% of a small number is a rounding error, and the pipeline costs more to build than it will ever save.
E
Part E: Where it loses, and what you provide
Making a decision cheap doesn't make it well defined. The losses say where it belongs more precisely than the wins do.
f10moderateFour jobs, six wirings on the fourth
On the one job that took judgment, it lost every way it was wired.
MeasuredThree jobs asked a question a written rule could settle, and it did well. The fourth needed weighing-up: its best of six attempts was 75%, against a cheap chat model's 87%.
Measured or publishedFrom the runs and the record
A gate
“Is this repository about AI?”
98.7%
Claude Opus 5: 95.9%
A fit
A screen
“Is this paper about AI tooling?”
95.8%
The keyword rule: 81.4%
A fit
A filter
“Could this be an attack tool?”
212 of 212
caught at the low cut-off
A fit
A tagger
“Which one of 31 labels fits best?”
74.7%
A cheap chat model: 87.0%
Lost
The four jobs, all reading short public text (repository descriptions, and paper abstracts for the screen), so the subject isn't what separates them.[5]
For whoever builds it: The test: could a careful person holding the written rule answer in a second? If so, it's a fit. If they'd have to stop and think, it isn't.
Evidence and objections
Measured The fourth job was picking one of 31 labels for each repository under a long rulebook. The chat model was Gemini 3.8 Flash at $0.90 per thousand, given the identical rulebook.[5]
A cheap classifier doesn't remove the need to define the decision well, and a poorly bounded question makes a bad system at any price.
f11moderate154 items, the same job four ways
Asked the right way, the same job scored better for less.
MeasuredAsked as 31 separate yes-or-nos it scored 68.2%. Asked as one pick-one question, 73.4%, at less than half the price.
Measured or publishedFrom the runs and the record
Jev
Cheap chat model
31 separate yes-or-no questions$0.31 per 1,000
68.2%
One pick-one question$0.12 per 1,000
73.4%
Pick-one, with the rulebook in it$0.12 per 1,000
74.7%
A cheap chat model, same rulebook$0.90 per 1,000
87.0%
Tagging a repository with one of 31 labels, asked four ways. Share matching either of two blind reference passes, with the price per thousand items.[5]
For whoever builds it: Choose the question type before you write the question. The default is rarely the right one.
Evidence and objections
Measured An audit of the first day's work counted every call: all sixteen used the yes-or-no form, including two jobs that weren't yes-or-no questions.[5]
Measured Asked as 31 yes-or-nos, the options never compete inside the model. They only get compared afterwards, in your code. Asked as one pick-one, they do.
Measured The rating type paid the same way on a filtering job: a described five-level scale, added beside nine yes-or-nos, left 42% fewer items for the expensive reader with nothing missed.
f12moderateSame 154 items
A flat list of 31 options beat a two-step hierarchy.
MeasuredSplitting the labels into 6 families and asking for the family first dropped the score from 73.4% to 63.0%.
Measured or publishedFrom the runs and the record
One flat list of 31 options
73.4%
Family first, then label
63.0%
Hierarchy plus five extra factor questions
59.1%
One flat list against the hierarchy, on the same items.[5]
For whoever builds it: Don't tame a long option list with a hierarchy. Fix the options.
Evidence and objections
Measured A hierarchy can never beat its own first step, and the first step is an abstraction. Asked for the family directly, it did worse than when the flat answer's own odds were simply added up into families.[5]
Objection, stated: the vendor publishes a cookbook for exactly this two-step approach. On this job it lost.
f13strongThree rulebooks, the same task and readers
Rewriting the rules moved the ceiling 18.7 points. Swapping models moved the best score 1.9.
MeasuredThe first rulebook capped agreement at 80.0%. Two rewrites took it to 98.7%, with no model changed.
Up 18.7 points from rewriting the rules. Every model swap on the same job, under the final rules, moved the best score 1.9 points. The scale starts at 70%.
The ceiling is how often two careful readers, labeling blind, agree with each other. No model can score above it.[5]
For whoever builds it: Spend the budget on the written rules and on scoring, not on the model. When a job looks subjective, it's usually under-specified.
Evidence and objections
Measured The first rulebook had 7 rules, the second 23 and the third 25. Same task, same data, same readers.[5]
MeasuredA rule change that went the other way: five explicit exceptions were added to a rulebook. The judging model went hunting for reasons to call things out of scope, wrongly cleared about 33 items it should have cut, and on a dozen wrote a reason that contradicted its own verdict. A list of exceptions teaches a model to look for exceptions.
f14moderateSame job, two question types
Its confidence sorted right from wrong on one question type only.
MeasuredOn the pick-one type it was right 93% of the time when sure and 32% when unsure. On the yes-or-no type, same job, being sure meant almost nothing.
Measured or publishedFrom the runs and the record
Pick-one question: right this often
When sure
93%
When unsure
32%
Yes-or-no questions, same job
About as right when unsure as when sure.
Don’t route by it
How often the top answer was right, by how sure the model said it was.[5]
For whoever builds it: Check that the confidence sorts right from wrong before you route by it.
Evidence and objections
Measured Sending unsure items to a person or a bigger model is the right pattern, but only where the confidence means something. Routing by the yes-or-no type's confidence would have sent the wrong items to the expensive reviewer.[5]
Measured The cut-off itself is a free dial: the odds are saved to a file, so trying forty cut-offs is arithmetic. Asking a chat model to "be stricter" costs a full re-run every time.
f15moderateTuned on 131, scored on a fresh 150
The design that won on the tuning sample lost on fresh data.
MeasuredOne big "is this about AI?" question scored best on the sample it was tuned on, then fell three points on fresh data. Seven small questions combined in code held.
Measured or publishedFrom the runs and the record
Tuning sample
Fresh sample, scored once
One big question
98.5%95.3%
Seven small questions, combined in code
98.7%
The scale starts at 90%, so the three-point drop is visible.
Agreement on the sample used for tuning against a fresh sample nobody had seen.[5]
For whoever builds it: Score once, on a fresh sample. A team that stopped at the tuning sample would have shipped the worse design with a better-looking number.
Evidence and objections
Measured The one big question scored 98.5% on the tuning sample and 95.3% held out. The seven small questions, with a short glossary of product names it didn't know, scored 98.7% held out.[5]
Try it
The demo is public, and so is its code. A bring-your-own-key build runs entirely in your browser: paste one OpenRouter key, and your browser calls the decision model and the chat model itself. Nothing is stored anywhere. Click any recommendation to see every term that built its score. It's at jevdemo.worthington.cloud.[6]
If a careful person holding the written rule could answer in a second, a decision model is a candidate. If they'd have to read, weigh and decide, it isn't.
It has to be fast, it runs at volume, and a chat model would be overkill.
Plain code needs a meaning-based signal before it can act.
A poor candidate
The job needs writing or explaining.
Deep reasoning is needed.
The categories are poorly defined.
A written rule in code already solves it.
A mature custom model clearly does better, and its cost is justified.
A mistake needs stronger controls than a probability and a cut-off.
Under other names the winning shape is everywhere: screening documents against criteria, routing a ticket to a queue, checking that a quoted passage supports the claim citing it, catching a prompt-injection attempt before an expensive model reads it, deciding whether a conversation needs a person. The losing shape looks almost identical from the outside: the same text, the same list of labels, and a rule that takes a paragraph of judgment to apply.
My reading, not measured
Custom machine learning isn't dead. Mature predictive models still make sense where large labeled datasets exist, where the problem stays stable, where a point of accuracy is worth real money, where numbers rather than text drive the answer, and where regulation needs a model whose behavior can be audited and reproduced. Nothing here was tested against a fitted model on its own ground. What changes is which problems get a model at all. A classifier used to have to justify a data-science project. Now it has to justify writing the question down and testing it, and that's a much longer list.
How to write the questions
One snap judgment per questionIf a person would need to think, split it. One big question scored best where it was tuned, then fell three points on fresh data. Seven small ones combined in code held
It reads you literallyA bare label like 'agent-harness' makes it guess what you meant. 'Runs, orchestrates or supervises AI agents' doesn't. When a wrong answer makes you explain what you really meant, that explanation was the missing half of the instruction
Give it the words it lacksIts confident misses were product names it had never heard of. A short glossary passed as reference data fixed a whole category of error that no rewording would have touched
Ask the negative tooA question like 'is the AI angle only marketing?' gives your code something to subtract. It cut false alarms on the gate more than any positive question added
Don't ask it to countIt's unreliable at arithmetic, counting and ordering dates. Pull the facts out with the model; do the sums in code, where they're exact and free
One piece of standing advice backfires if read loosely. "Combine in code" means combining separate factors, not re-applying rules the options already state. Doing both cost four to five points every time.[5]
What this doesn't claim
That these scores are accuracy. They're agreement with a reference reader that is itself a model.
That any of it holds on insurance claims, support tickets or medical records. It's one kind of public text, from one bench, over three days.
That the economics are measured. The ladder, the falling floor and the Jevons reading are how I read the numbers.
That fast adoption means lasting use. The adoption figures are one gateway's first day, and a model can be dropped as fast as it's picked up.
That it's safe on hostile input. Text written to steer a classifier can steer it.
That it's private. It's an outside service, so anything sent to it leaves your machine.
Written down first
No guesses were registered for this build. What was written down before any data was drawn was the method: the rule for each job, saved to a file first; reference labels written to files by a reader that saw no other model's answers; and a design frozen and scored once on a sample the tuning never saw.[5] Here's how each held.
“The rule goes into a file before any data is drawn.”
Kept
Every job's rulebook was saved first. The first one turned out to be the weak part, which is how the ceiling result was found.
The same question asked twice on the same 154 items scored 73.4% and 72.7%, which is one item. No claim here rests on a gap that small.
What broke on the bench
Every idea tried on the bench, and what became of it.
Killed
"Jev isn't on OpenRouter." The first conclusion of the day. The catalog listed 447 models and none was Jev. It was live the whole time, unlisted, behind its own endpoint. Cost: a morning.[2, 5]
Jev's top three as a shortlist for a chat model. Same score or lower, at a higher cost.
Sending flagged items to Claude Opus 5 as the judge. No gain, at 3.5 times the cost.
A majority vote of three chat models. Below the best one alone.
Seventeen worked examples in the instructions. The score went down, from 87.0% to 85.1%.[5]
Changed
The shared variable. One setting did two jobs in the shipped script, and 1,854 items went for expensive review instead of about 70 (f7). Split into two settings.
The missing nonstop question. Written and weighted in the rebuilt demo (f4).
The rating scale. Rewritten so no two levels can both be true (f5).
The tagging scores' basis. Corrected on Sep 20, 2026 to "matches either blind pass," the basis every tagging figure here uses.[5]
Held up
The gate on fresh data. 98.7%, against Claude Opus 5's 95.9% (f9).
The second-opinion flag. 15 of 20 errors caught, on the same 154 items (f8).
Running it twice. 8 answers of 10,714 changed (f9).
The low cut-off. No real hit dropped in any measured run (f6).
Twice, the ruler was a contestant
The same mistake happened twice in one evening, in two unrelated experiments. Both times a headline figure was a model measured against something it had produced itself. Both times the number flattered it, and neither was caught by review.
A careful readerrulebook open, unlimited time
96.3%
The same model, a normal API callbeside every other contender
81.5%
15 points of its 24-point lead came from how it was asked, on the same 54 items.
The same model, the same rules, the same 54 items. The first number was that model working as a careful reader with the rulebook open and unlimited time. The second is the same model through a normal API call, beside every other contender.[5]
Fifteen points of its twenty-four-point lead were how it was asked, not which model answered. And underneath it, the answer key for that job had been written by the same model working the same careful way, so 96.3% was never scored against an independent standard. It was scored against its own house style. Four hours earlier, on the other job, the answer key had matched the cheap model's own verdict on 99.6% of rows, 10,672 of 10,713.[5]
It's worth holding the vendor's benchmark to the same two rules. Its reference labels were averaged from two frontier chat models, and its workflows were written by its own team.[3, 4] That doesn't make the numbers wrong. It makes them the vendor's numbers. One news roundup of published field measurements tallied real-world speedups of 1.16 to 6 times.[7]
Limits
Agreement, not accuracy. Every score is how often the model matched a reference that is itself a model.
Small samples. 118 to 154 items for every scored comparison, plus two full passes over the 10,714 repositories. A 2 to 3 point gap is noise.
One corpus, one domain, one bench. Public code repositories and research abstracts, Sep 19 to 21, 2026, one operator.
The demo is an illustration. Its customers and airline are made up, and its screens are one turn for one customer. Its decision-model cost is an estimate from token counts at list price.
Speed for a live product was measured once, lightly. The experiments ran in batches. The demo is the only live measurement: a handful of turns from one laptop, landing around 0.6 seconds for twenty-four questions. The earlier thirteen-question build answered in about half that. The questions are cheap, not free. No load, no concurrency, one network.
Hostile input and privacy weren't tested. Both ruled out some of the most attractive uses before they were tried.
How it was made
Personal time, personal hardware, public data. Two dozen numbered experiments ran on Sep 19, 2026, each with its sample size, its random seed, its cost and the file holding every individual answer.[5] The model was typesafe/jev-1.13 on OpenRouter; the dated build that answered was typesafe/jev-1.13-20260917. The demo was built the next day on the same laptop, then rebuilt on Sep 21 to ask 24 questions instead of 13 and rank 770 packages instead of 10 offers. The chat model in the demo is Claude Haiku 4.5.[6]
1,960decisions in 4 seconds for $0.0028: the first thing run, before any tuning. 49 repositories, 40 questions each
About $4across every model: 25 cents on Jev, 78 cents on Gemini Flash, $1.13 on Muse Spark, about $1.68 on Opus 5 (costed from its tokens at $5 per million in and $25 out). One run estimated at under a dollar came to about $2, because one vendor bills its hidden reasoning
Nineblind reference passes by Claude Fable 5.1 across the day, about 1.1 million tokens, two per sample so the second gives the ceiling
13 → 24questions per turn in the first and rebuilt demo. The first build's timings are medians over eight scripted turns (0.23 s for Jev, 1.7 s for the reply); the rebuilt build's are single captured turns
First build, switched on
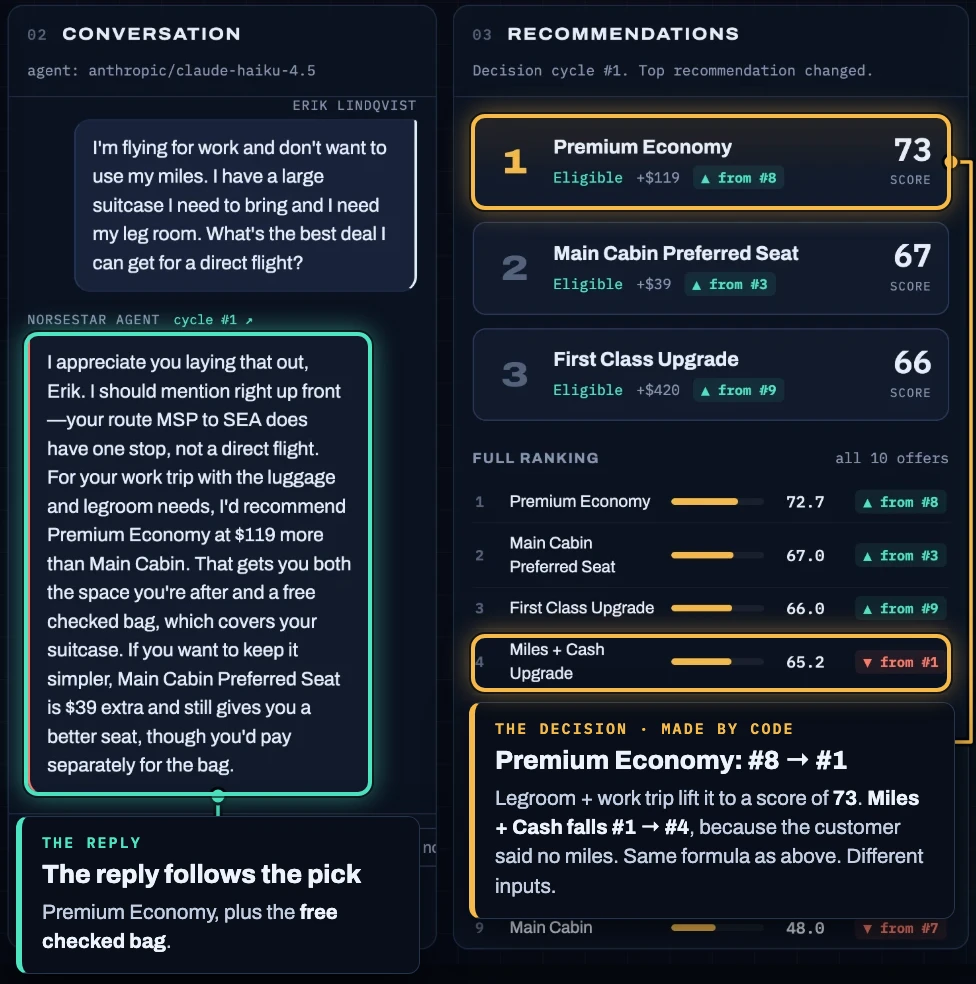
The first build, captured Sep 20, 2026, before the nonstop question existed and before the offers were rebuilt into packages. Kept because f4 rests on it.[6]
The video at the top was made with the video kit used for every explainer on this site. Claude wrote and animated it in code and voiced it as Earl with ElevenLabs, and Rick reviewed it on a page that pins his notes to moments in the video. The Oct 20, 2026 cut is the second: re-voiced and redrawn for the notebook design.
AI disclosure
The prose here was written by an AI, Earl (Claude Opus 5.5), under Rick's editorial direction, from the earlier revisions Claude wrote in September. Claude, working in Claude Code on Rick's laptop, also designed and ran the experiments, built the demo and drew the figures. Rick owns the questions, the jobs, the decision to publish the losses and every editorial call.
No model scored itself, but every score rests on a model's judgment: plain code compares each answer to reference labels that Claude Fable 5.1 wrote blind, to files, before scoring. The costs are each service's own count or bill, and estimates are labeled as estimates. Jev, Gemini 3.8 Flash, Muse Spark 1.3, Claude Opus 5, Claude Sonnet 5 and Claude Haiku 4.5 only answered.
So you're trusting the blind reference passes, the stored answers, and the rule that the design is scored once on fresh data. Each is named under Sources.
Versions
Rev 1 Sep 20, 2026: first publication.
Rev 2 Sep 20, 2026: rewritten as a guide, with the three question types first and each experiment under the point it proves.
Rev 3 Sep 20, 2026: the demo leads, a decision model reading a customer's message, code deciding and a chat model talking.
Rev 4 Sep 21, 2026: the demo's screens recaptured on the rebuilt 24-question demo. The nonstop lesson gained its repair.
Rev 5 Sep 22, 2026: rewritten around the building block, opening on the adoption figures, then the price argument, with the demo as evidence.
Rev 6 Oct 11, 2026: links to the head-to-head with OpenAI's decision model and to the build of a screen that disappears.
Rev 7 Oct 20, 2026: the explainer video at the top, narrated by Earl.
Rev 8 Oct 20, 2026: moved to the notebook design. The story comes first, every result sits beside a figure drawn for it, and each statement is marked as measured or argued. The results are numbered f1 to f15, the price argument sits on graph paper as one part, "How I built it" opens with what was written down first, and the sources are numbered by first appearance. The title changed from "The model that can't write a sentence" after a title test, and the cover is now a photograph in the house style instead of a demo screen. Every number was checked again against the run files, and four details changed. None changes a result. The 31-question tagging run cost $0.31 per thousand, not $0.29. The answer key on the attack-tool job matched the cheap model's verdict on 99.6% of rows, not 99.4%. In the demo, the decision model itself took 595 ms; 612 ms was the whole decision step. And of the ten items that fooled all three chat models, eight got the same wrong label, not all ten.
SourceVercel. "Jev is the fastest-adopted model in AI Gateway history," Sep 18, 2026. Quoted: "By hour 24, nearly 13% of paid teams were using it. That's 2x the GPT-5.6 family and more than 6x Fable 5.1's share." The metric is the share of paid AI Gateway teams; the post publishes no request or token counts. It repeats TypeSafe's benchmark, rounded to 194 and 445, and attributes it. vercel.com/blog/ai-gateway-jev-model-launchvercel-launch
SourceOpenRouter. Model page and provider listing, checked Sep 22, 2026: $0.042 per million input tokens, $0 per million output tokens, 32,000-token context, released on the gateway Sep 18, 2026. Usage from the public rankings feed (openrouter.ai/rankings), day view dated Sep 21, 2026: 82,379,677 requests, rank 1 of 556 models by requests and 13 of 556 by tokens; daily requests 28.2M (Sep 18), 52.6M (Sep 19), 64.4M (Sep 20), 82.4M (Sep 21). The model is served through a dedicated decisions endpoint and doesn't appear in the gateway's general model catalog, which is what cost the first morning. openrouter.ai/typesafe/jev-1.13openrouter
SourceTypeSafe home page, checked Sep 22, 2026: "193.6x Faster, 444.6x Cheaper," footnoted "based on workflows for System One tasks." The eval site, evals.typesafe.ai, lists four workflows (security incidents, agent-trace observability, invoice processing, customer service) and says the reference labels "are generated via an average of the responses of GPT-6 Astra and Claude Fable 5.1, both at high thinking." Graded: the vendor's own evaluation of its own model. typesafe.aitypesafe-home
SourceTypeSafe. "Introducing System One Models and Jev," Sep 15, 2026. On the name: "We named Jev after William Stanley Jevons." On the benchmark: the multiples are expected to be "on the higher end of real world gains," and the workflows "were made by individuals on our model capabilities team, so some bias could exist." The "System One" name is drawn from Kahneman's Thinking, Fast and Slow. The three question types are defined in the documentation at docs.typesafe.ai. Used for how the product works, not for any claim about accuracy. typesafe.ai/blog/introducing-system-one-models-and-jevtypesafe-launch
DerivedExperiment ledger, Sep 19, 2026: 24 numbered experiments (E0 to E24), each with its sample, seed, comparison, result, cost and per-item answer files, plus the scoring-basis correction of Sep 20, 2026 (tagging figures on the "matches either blind pass" basis: 68.2, 73.4, 74.7, 87.0). Samples of 118 to 154 items for every scored comparison; two full passes over 10,714 repositories; reference labels from nine blind Claude Fable 5.1 passes written to files. Every figure here recomputes from the raw files. Total model spend about $4.ledger
DerivedNorseStar Air demo: source at github.com/WorthingtonCloud/norsestar-air, live at jevdemo.worthington.cloud. Timings measured on the server as full round trips; decision-model tokens as reported by the API and priced at list; chat-model cost as billed by the gateway. First build captured Sep 20, 2026 (13 questions, 10 offers); rebuilt demo captured Sep 21, 2026 (24 questions in four parallel calls, 770 packages). Untouched captures and overlay source kept.norsestar
SourceThe Cherry Creek News, "Jev, TypeSafe, and the benchmark, checked," Sep 21, 2026. A secondary compilation of published real-world measurements, tallying speedups of 1.16 to 6 times, including a TypeSafe employee's launch-day test that routed one decision step of a real pipeline through the model (1.16 times faster, cost per ticket down 30.1%). Cited as one outlet's tally, not as a reproduction.cherry-creek